

How CodinGame Survived a Reddit Hug of Death
Last Monday afternoon, a link to CodinGame was posted on Reddit. It gained a lot of success and resulted in what is called a hug of death. Our platform went down for 2 hours because of the overwhelming amount of new visitors.
Internet is Beautiful
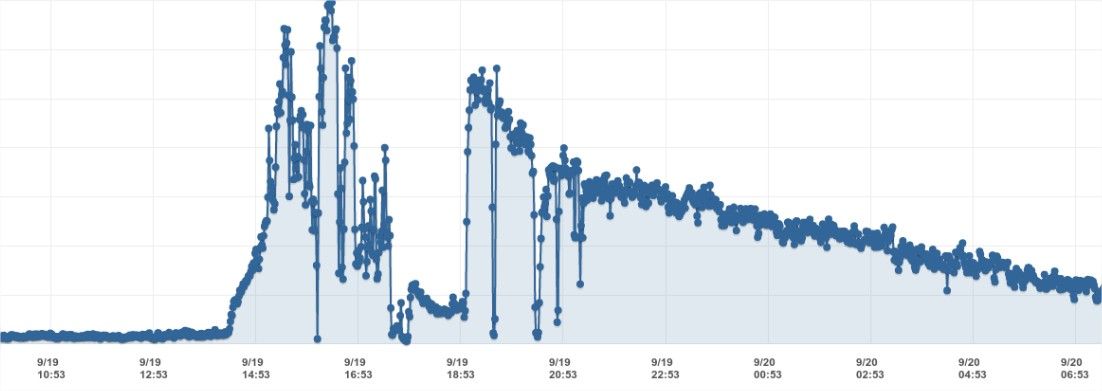
This was so far a normal day. We were working on the last preparations for the next multiplayer coding contest Hypersonic to be held this Saturday. Around 2pm, Nico, our CTO, shouted that we were suddenly receiving a lot of traffic.
A link to our starting page had been posted on the subreddit /r/InternetIsBeautiful under the title “Learn to code writing a game”. The traffic was already 10 times higher than usual and we were rejoicing.
After a few minutes watching the incoming traffic grow more and more, we began to notice some lags…
When will it stop? Can we support the load?
From Excitement to Panic
After some quick monitoring, we realized the CPU of the database server was already capped. We decided to multiply the capacity of our RDS (Amazon Relational Database Service) by 4 on AWS. It took 30 minutes at the end of which it interrupted the service completely. We had no choice.
After that change, the server was able to take in a lot more load, lags came back again pretty soon, when some other point of the architecture started to fail too. Now the front-end servers were failing.
The CodinGame platform normally uses two application servers hosted on EC2, behind a load balancer. So we tried scaling up by doubling that number (we eventually reached 6 servers in the end), but some of them started to crash. We tried relaunching them, to see them fail again after a short time.
The platform was becoming barely usable. What a waste, all this traffic to a dead/lagging site…
Reddit had put CodinGame to its knees.
Crisis Management
While activity on our social media channels started to increase, the CodinGame chat was buzzing with questions. The community regulars were doing their best welcoming newcomers.
The chat server was also under heavy load and wouldn’t accept new users (more on this later). Forum didn’t last long either. We took the opportunity to offer an AMA (ask me anything) in the comments of the Reddit thread.
At the same time, a Twitch streamer was desperately waiting to do a Clash of Code session. Things were looking bad and everyone was preoccupied. Reddit finally tagged the post with “Hug of Death” so visitors didn’t end on a dead site.
The End of the Tunnel
After two long hours, we managed to get the servers back and running, and we asked the Reddit moderators to bring back the thread. Traffic came back as a wave as the thread was reposted on Hacker News and other tech news sites. And lags again. Something was taking down our servers and we couldn’t find what. Finally, we put in place a script that would reboot a server each time it failed so we maintain the service over the night.
Reddit's hug of death on CodinGame, it reminded me this moment from Silicon Valley: https://t.co/Xwp4Q8FVfV Still on Reddit frontpage!
— Maxime Chéramy (@MaximeCheramy) September 19, 2016
On Tuesday afternoon, when things had calmed down, we took the time to come back on what had happened. Traffic had been crazy: we got as many new users in one day as during the last two months. There had been technical failures. Understandable failures but to be taken care of.
Post-Mortem – What Went Wrong
1) The main bottleneck of the CodinGame platform is the RDS database. We centralize every information on CodinGame there, all tangled. We cannot distribute the database without setting up separate servers splitting users, for instance by region (America, Europe, Asia). This is the major scaling issue.
Solution: the short term action we’ll take is to investigate caching solutions, distributed caches between our application servers.
2) The second issue we’re currently following up is a memory leak on the application servers. This bug occurs when a server is under heavy load and eventually leads to a crash.
Solution: track the bug, kill the bug.
3) We host The CodinGame forum on a really small machine. It is poorly integrated on the platform through an iframe so that every user on any page of the site sends an SSO authentication request to the forum. The number of queries that were sent to this instance capped the CPU, and just like that, the forum was no more.
Solution: Better integrate SSO between the website and the forum to avoid unnecessary requests. Migrate the forum on a tougher machine.
4) This very blog crashed, simply because it was… hosted on the same machine as the forum, that maxed out the CPU.
Solution: Separate applications in different containers/machines.
5) The CodinGame chat server did exactly what it was expected to do. It failed under heavy load. It uses XMPP over WebSocket, with a custom client built on top of stanza.io, and a back-end built with Prosody. Prosody is a really cool back-end built with lua. But it has the slightest problem: it is single-threaded and non-distributable. So, as expected, the server process quickly reached 100% of a single CPU core and started to lag badly and act erratically. It didn’t crash, but wouldn’t take in new users.
Solution: Switch our back-end solution to a scalable one, such as eJabberd or MongooseIM.
6) Last point of failure in this real world scalability test: the push server. We use a websocket connection to push data to the client, triggering diverse events (notifications, mostly). This server had a limitation of open file descriptors, arbitrarily set to 10K. We set it to 100K and it started working again, accepting up to 60K simultaneous connections (this is the best estimation we have of the number of open tabs at that moment) before it went night-night.
Solution: This is an Embarrassingly Parallel Problem, and it should have been a scalable pool of servers behind a load balancer from the beginning.
We took a blow, but we’re back on our feet, stronger than ever. We’ll be happy to answer any question you might have about this special event. Don’t hesitate!
Welcome to all the new users!
Comments
Log in to commentEarlier comments
Learn, grow, and keep up the good work!
I was a proud new member on that day! Devschool is behind you guys 100%! You did an awesome job dealing with your pants on fire.
Thank you for your kind words! Welcome and make yourself at home :)
Interesting, any plans on migrating to google compute engine? Seems like aws is a bottleneck in general ;)
We have a plan to try it starting next month, yes. But I am not sure aws was the issue this time.
I was part of the Reddit rush, apologies for the chaos but so glad to find this site.
Woo can we get a Zerg Achievement?
ahah that would be fun: "Member of the Swarm" achievement
Glad you're back.
Where you use websocket to push only, SSE (Sever Side Event) could be a better solution. I guess other alternative are the Pub/Sub solution sell by AWS, Google Cloud Platform, PubNub... or try to use a special XMPP channel and share your improvement between chat and notifications.
Thanks for the tip. We have a plan to make our websocket server really scalable. I'll make sure we investigate SSE as well when we do our study.
lol i was a redditer that clicked the link
As a recent newbie (pre-Hug of Death) I posted the link on imgur in a related post, but think it might have been *just after* your server failures: http://imgur.com/gallery/cB...
Still, hope I didn't indirectly contribute to any stress. Amazing site and keep up the good work! :)
Excellent article, thanks for sharing...Reddit should make this a sticky post on their site for everyone to reference.
OH WAIT ;)
I've been working a lot on performance under heavy load where I currently work. We had a similar problem where the pipeline between the application servers and our rds instance would get flooded, and then the database connection handler would timeout and the application server would crash. We've since tuned it to recover without needing a restart, but it was a tough nut to crack.
Great post. I've been using this site for a long time and you guys keep coming up with more and more great content. I love this website! :D
Thank you for the kind words afish!
What kind of numbers where you hitting in terms of individual users and request? I've used various load testing software to simulate user traffic conditions of 600m+ to our applications.
For a quick setup, higher cost, no infrastructure to worry about Loadster is a solid option for bursting really big numbers.
https://www.loadsterperform...
For a slower setup, cheap cost (when setting up on your own aws / linode nodes ect..) Webserver stress tool by paessler is competent
https://www.paessler.com/to...
*Note: I am not affiliated with either of these products and our my personal opinions.*
Keep up the good work, love the site and have directed many a junior and senior developer your way!
* 600m+ per day...
Lol,
> uses Lua
> talks about performance
...
nuff said :D